22 Sep 2026
Jev vs Laya: the same model deciding, at ten times the speed
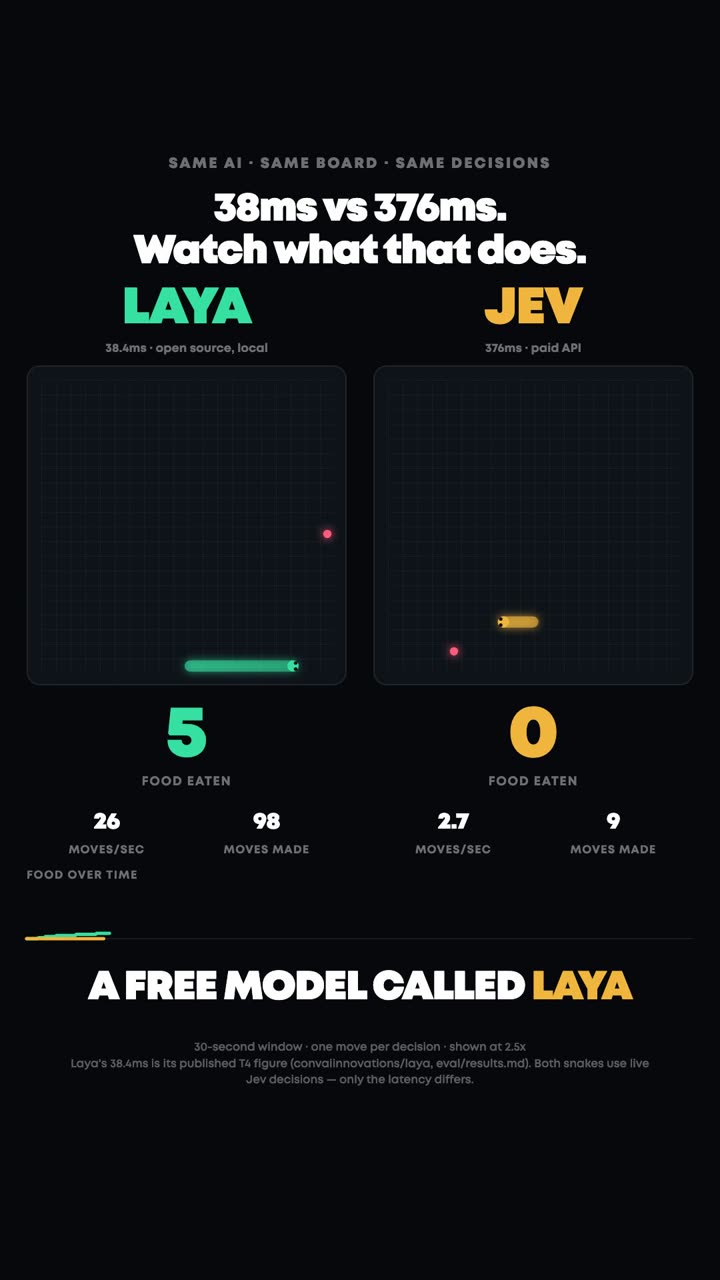
Jev vs Laya. Same board, same food, same decisions. One ate 47. The other ate 4.
Open10,000 Skittles, sorted by colour one at a time.
10,000 Skittles, sorted by colour one at a time. Each one is a short description that never names the colour, like 'coloured as a stop sign is', so the model has to actually decide. Two models, the same 10,000 items in the same order, one item per request, 20 requests in flight on both sides.
Jev is TypeSafe's new decision model. It does not write text; it returns one of the options you give it, with a probability. It cleared the bowl in 3m41 for 15 cents. Claude Sonnet 5, with reasoning switched off so it was as fast and cheap as it can be, took 17m55 for $1.86. That is 4.9 times faster and 12 times cheaper.
Jev got 300 of the 10,000 wrong and Sonnet got 57, so Jev was 2.4 points less accurate. After posting I went back through the misses, and most of Jev's came from one description I wrote. I now think that was a faulty input on my side rather than the model, and I am re-running the test. Until that is out, treat the accuracy gap as unsettled.
They answer on different endpoints, so this compares two products, not two identical setups.
| Entrant | Tool | Time | Cost | Verdict |
|---|---|---|---|---|
| TypeSafe Jev 1.13 | OpenRouter, System One | 3m41 | $0.15 | 97.00% correct, 300 wrong |
| Claude Sonnet 5 | OpenRouter, chat completions | 17m55 | $1.86 | 99.43% correct, 57 wrong |
The reels are the test bench. The real work is picking the one job in your business worth handing to AI, building it properly, and keeping it running. That’s what I do as your AI partner.
Jev vs Laya. Same board, same food, same decisions. One ate 47. The other ate 4.
Open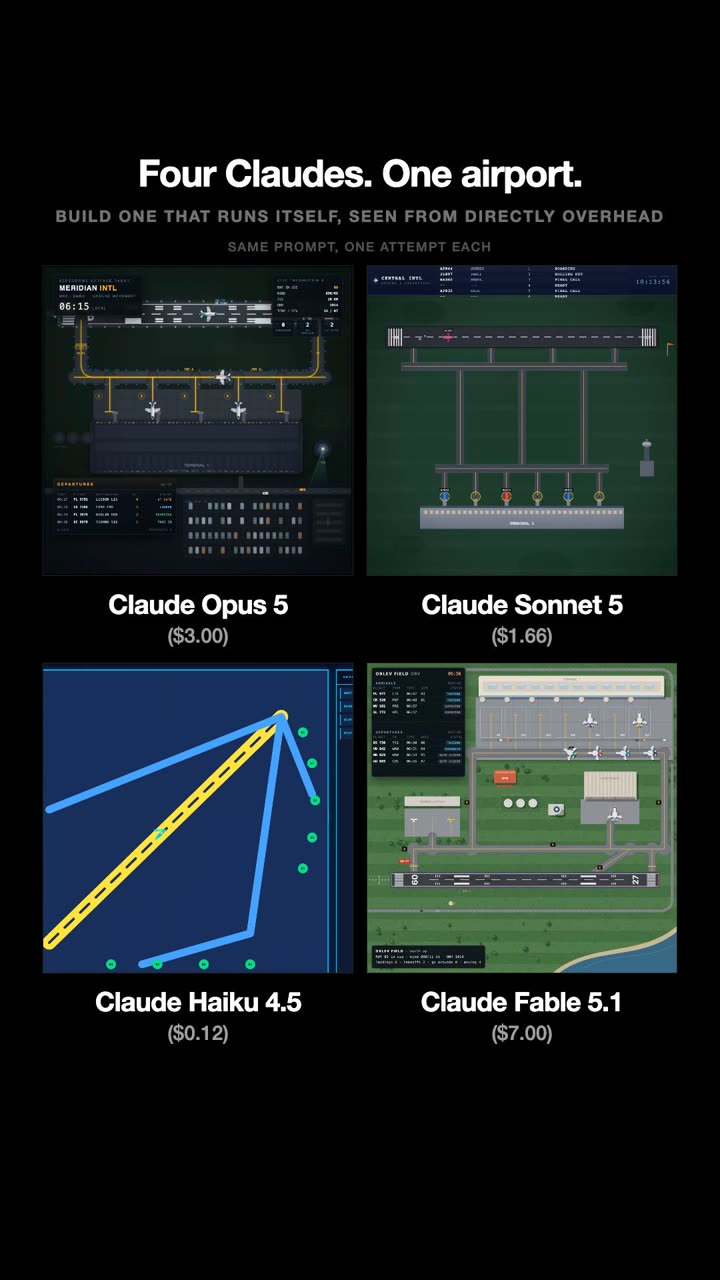
Four Claudes. One airport.
Open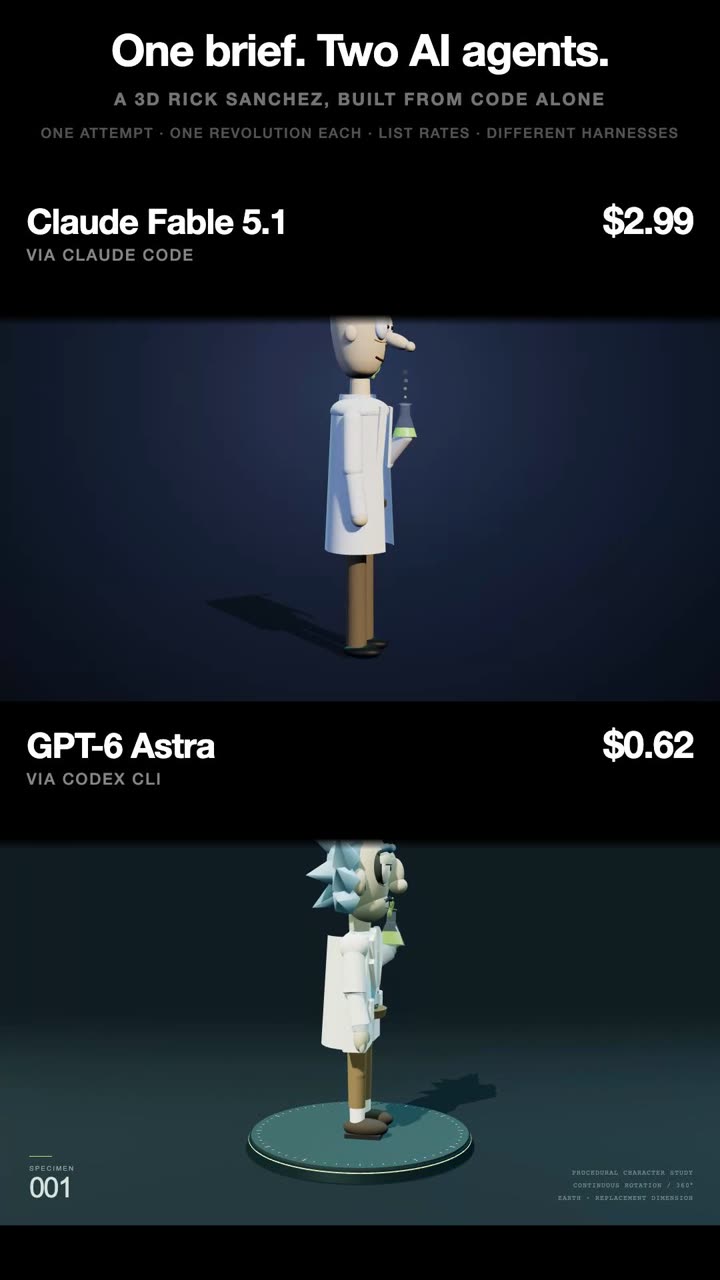
One brief to two AI agents: build a 3D Rick Sanchez out of nothing but code.
Open